llm-visuals
Share on:
Enter Your Mastodon Instance
Copy the link below to share to Mastodon
https://terminaltrove.com/llm-visuals/
A live terminal dashboard for local LLMs running on your machine.
Script Preview
Review this script before executing in your terminal.
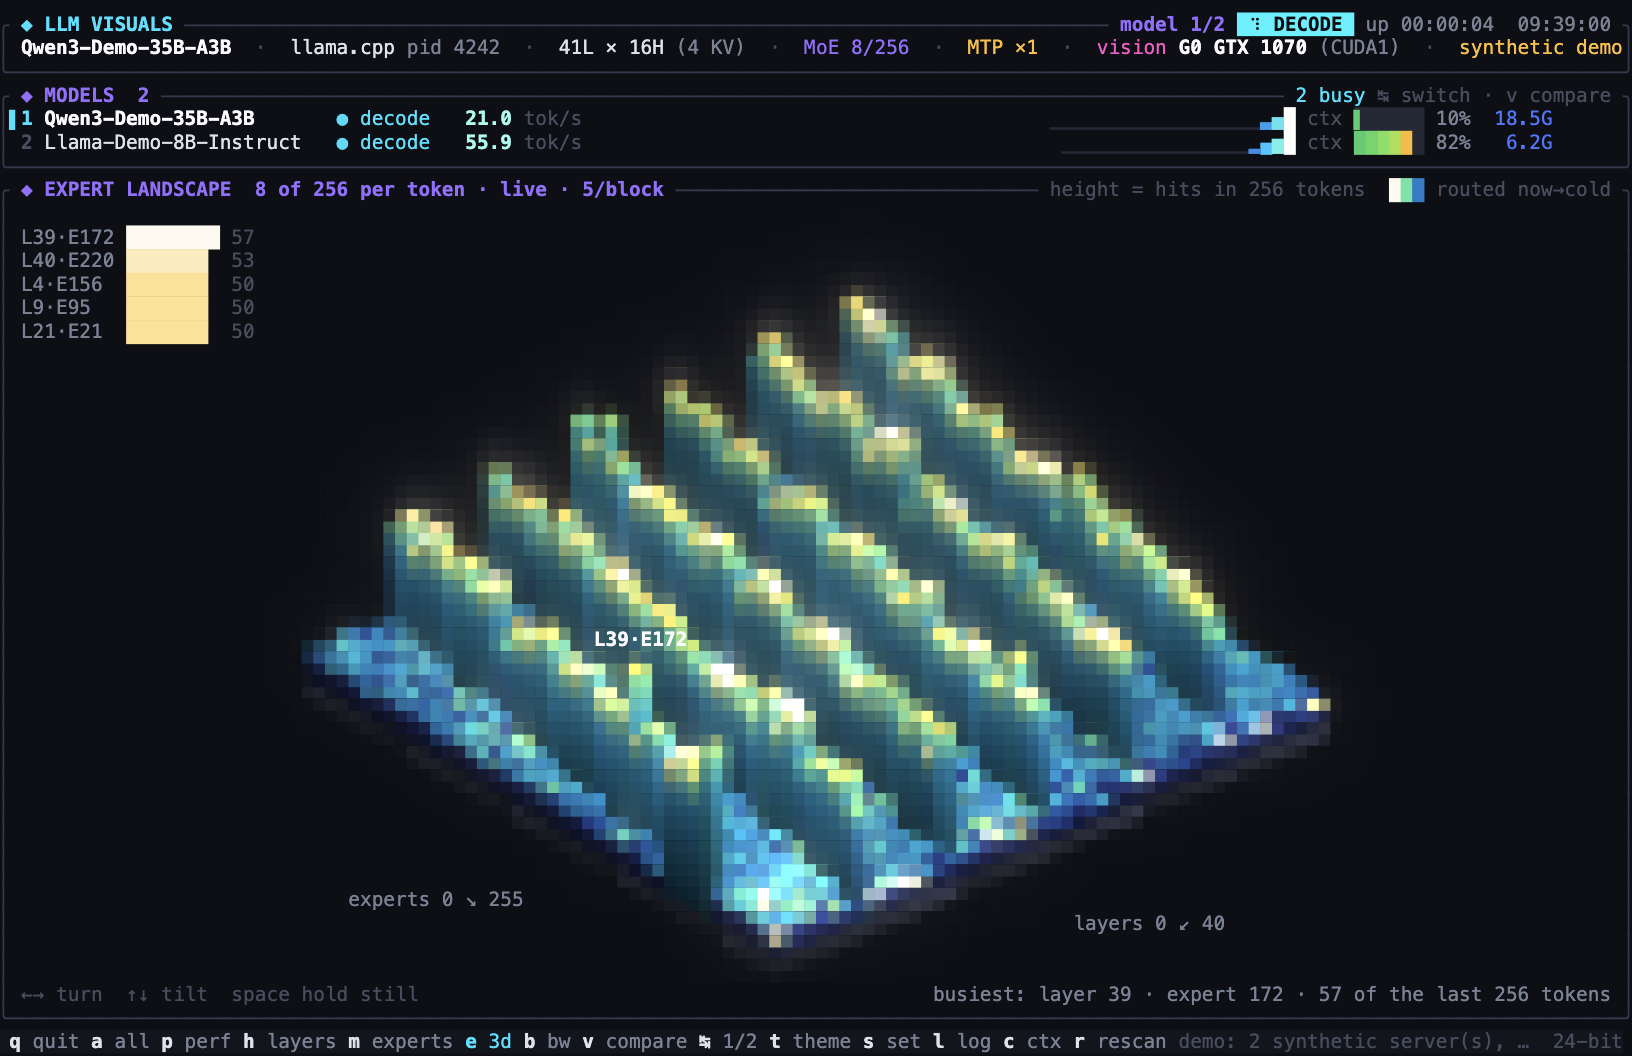
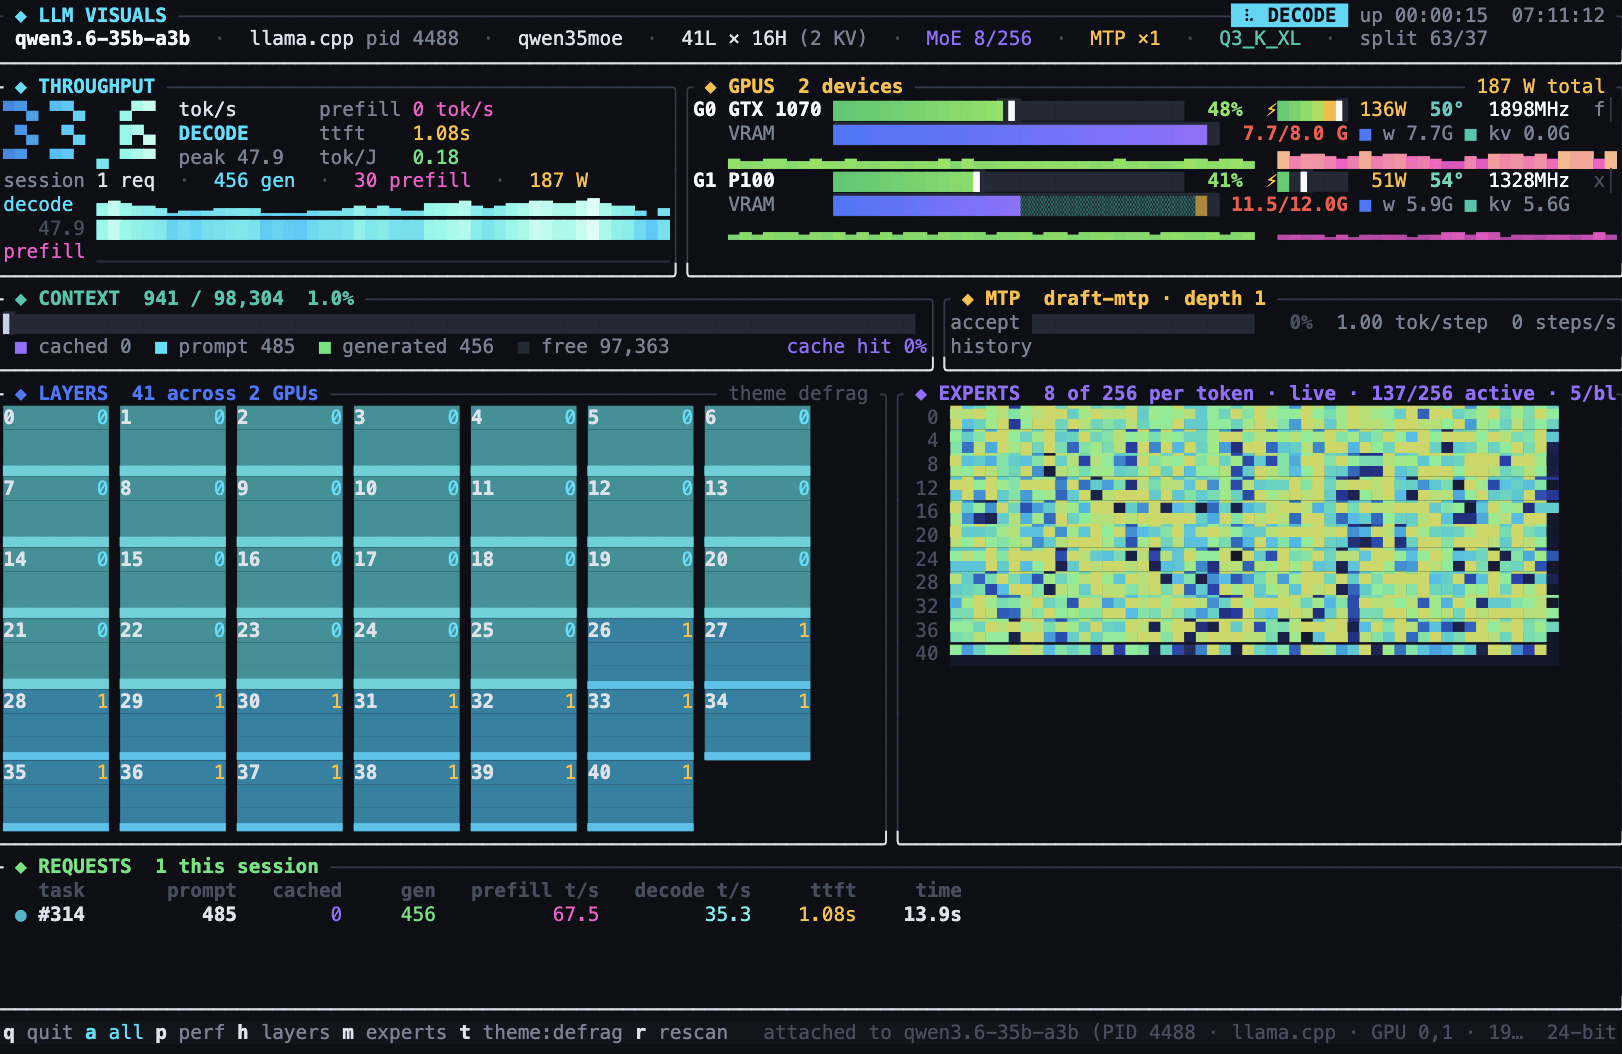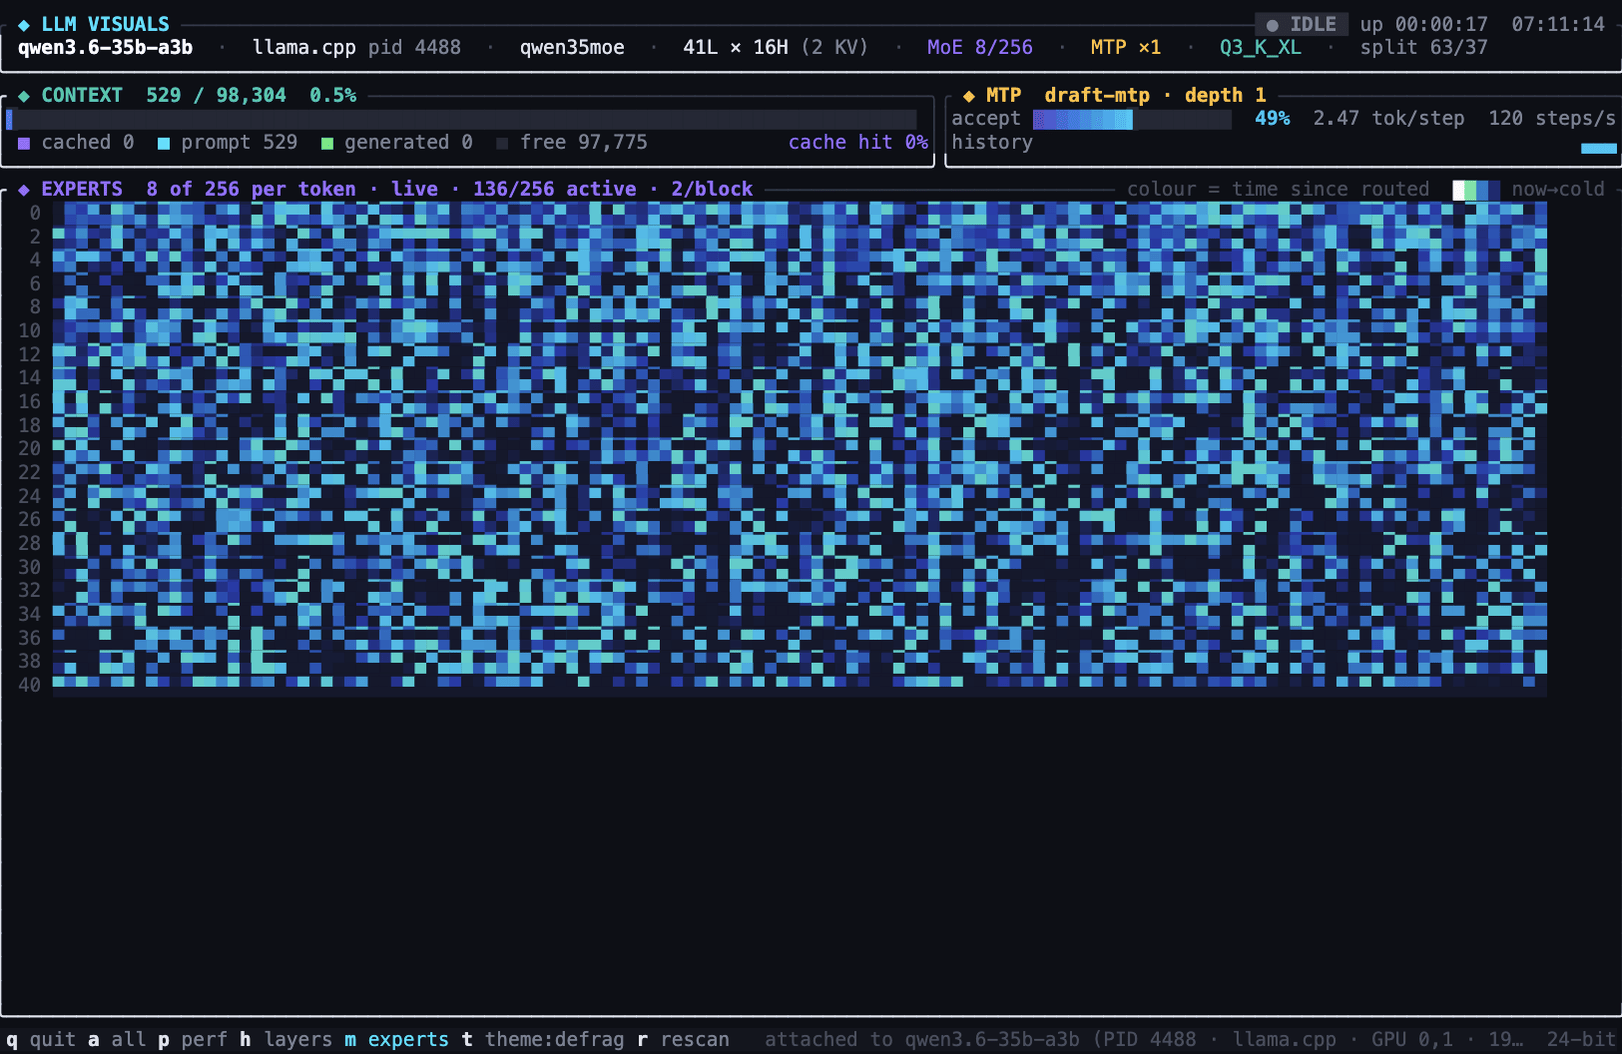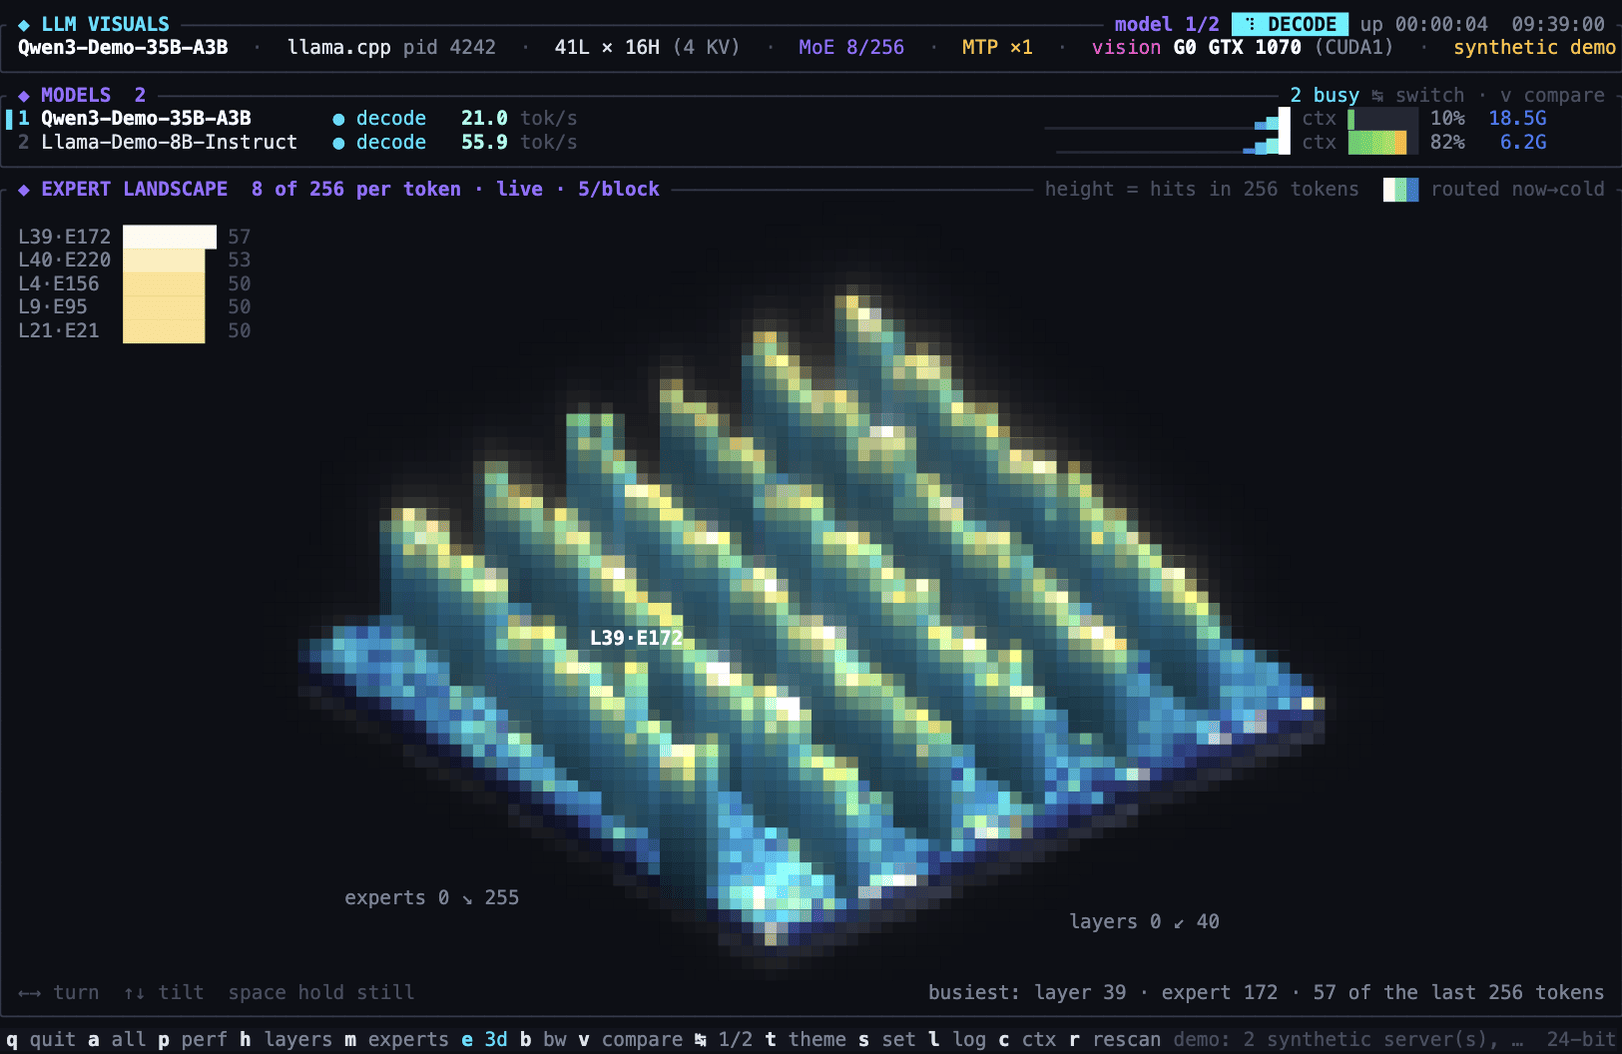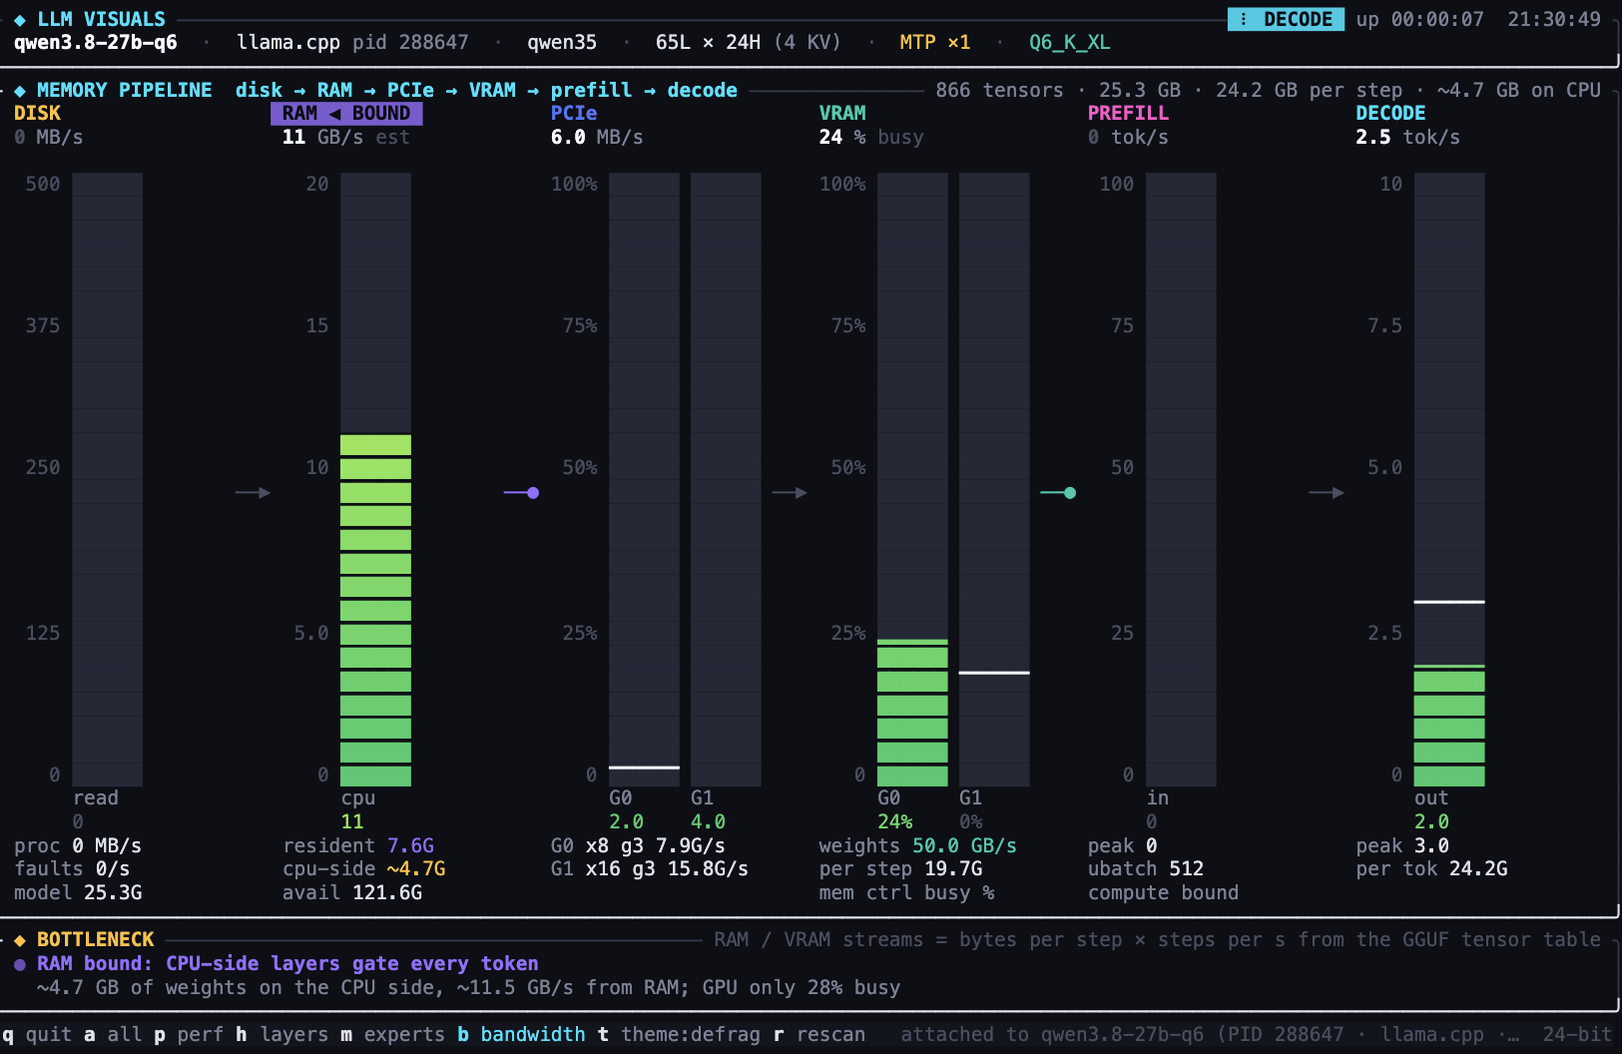
llm-visuals is a terminal dashboard for monitoring active local LLM inference and GPU performance.
It detects running inference servers, including ollama, and displays prefill and decoding speed measured in tokens per second, and time to first token with context usage and GPU memory and load statistics. The performance view combines throughput histories and it has the Mixture-of-Experts (MoE) balance view showing the GPU load of each expert in active inference.
One other useful view in llm-visuals is the bandwidth section that indicates which part of the hardware pipeline is bottlenecked or actively decode / or prefill bound. The active experts can be visualized in 3D to give the perspective of the current GPU inference activity.
For machine learning engineers, researchers, inference engineers and software engineers that running local models, llm-visuals is useful to help with investigating inference slowdowns and watching how requests use available hardware.